Related Topics:
Asus Esc8000a E13x Server-
Current Status of AI Server Development
Dell, HPE, Lenovo, and Supermicro are riding record AI server demand, but winning enterprise customers requires more than just Nvidia chips. With GPUs standardized around Nvidia, vendors compete on AIOps, liquid cooling, and deployment services as enterprises ramp up inference in 2026. A comprehensive report by Global Market Insights Inc. The market is expected to grow from USD 167. 88 billion in 2024, at a CAGR of 34. This surge is driven by rising demand for AI applications, advancements in AI technology, cloud and edge computing expansion, and big data analytics. The AI server market is projected to reach US$245 billion in 2025 and is expected to grow to US$523 billion by 2030, driven by rising demand for Generative AI (Gen AI) tools like ChatGPT, Perplexity, and Claude, ABI Research said in a report. Enterprises increasingly deploy AI models in-house.
[PDF Version]
-
Does AI require server configuration
Server needs vary depending on the AI phase: Training: Demands the most resources (high-end GPUs, large RAM). Inference: Requires less power than training, but still needs optimized hardware. Choosing the right AI server setup for your workload is crucial to ensuring optimal performance and scalability. In this comprehensive guide, we will explore the key factors to consider when selecting an AI server setup, including understanding your AI workload requirements, determining the right. AI, or artificial intelligence, is changing the way organizations and businesses handle data by incorporating automation of complex calculations, introducing new advanced applications, and fulfilling computational demands like never before. Role: GPUs are very. A server for local AI inference should not be chosen by the most expensive graphics card, but by whether the model, working cache and parallel requests fit into video memory, and whether the system has enough CPU resources, PCIe lanes, power and cooling. For a small model and a few users, one.
[PDF Version]
-
Huawei AI Server Liquid Cooling
Huawei developed a full liquid cooling solution, reducing the power consumption by 96% and cutting the PUE from 2. This increase in power density has posed an unprecedented challenge to conventional cooling systems. To address this challenge, Huawei. Advanced AI chips are generating more heat in data centers, necessitating improved cooling solutions. Proposed techniques include circulating water through cold plates, circulating boiling liquid through cold plates. Liquid cooling is essential for AI-driven data centres, efficiently managing the extreme heat generated by high-density AI server racks. It offers up to 15% better energy efficiency and reduces cooling costs compared to traditional air-cooling systems The technology also enables higher server. This AI revolution is built on incredibly powerful computer chips. But there's a catch, a hot one. These chips, especially the GPUs that are the workhorses of AI, are generating a staggering amount of heat.
[PDF Version]
-
P40 multi-GPU AI server
We've built a homeserver for AI experiments, featuring 96 GB of VRAM and 448 GB of RAM, with an AMD EPYC 7551P processor. We'll be testing our Tesla P40 GPUs on various LLMs and CNNs to explore their performance capabilities. We'll also share our approach to cooling these GPUs. more Audio tracks. Tesla P40 24GB for possible local AI server build. 0 16x lanes, 4GB decoding, to locally host a 8bit 6B parameter AI chatbot as a personal project. Would. This guide details the configuration steps required to properly set up multiple Tesla P40 GPUs in passthrough mode for Ollama on an Ubuntu 22. 04 VM running on a Proxmox host. Edit your VM configuration file (/etc/pve/qemu-server/YOUR_VM_ID. It runs 30B+ models that gaming GPUs under $200 can't touch. The catch: no display output, no fans, no native FP16, and you'll need a cooling mod. Pre-installed NVIDIA drivers, Linux/Windows support, and flexible CPU–Memory–GPU combinations make it ideal for AI training, inference, rendering, and scientific computing. Equipped with a substantial 24 GB of GDDR5 VRAM, this GPU is an intriguing option for those looking to run local text generation models.
[PDF Version]
-
AI call not connected to server
Call reconnect(failed_only=True) to retry failed servers, or reconnect(failed_only=False) to restart all servers. I have two agents deployed in Azure AI Foundry (Switzerland North), both using a shared GPT-4. 1 model deployment: Agent 1: apples-agent Has an MCP server configured The MCP server exposes one tool: returns the number of apples in my basket Works correctly when invoked directly - returns expected. When I try to setup the connection in the playground it seems to take a long time to connect to the MCP server (if it really is, not sure) and then goes to the page to list the tools and errors out with “Unable to load tools”. MCP Server just has a single function to create a file Server Implementation @Tool(name = "Create File", description = "Create a file with the provided fileName on the file system") public String createFile(String fileName) {. Make sure you call 'connect ()' first. UserError: Server not initialized. Make sure you call 'connect ()' first. · Issue #446 · openai/openai-agents-python /agents/mcp/server.
[PDF Version]
-
Germany Digital Huawei AI Server
[Munich, Germany, April 30, 2025] On April 29, 2025, at the 4th Huawei Innovative Data Infrastructure (IDI) Forum in Munich, Germany, Huawei launched the AI Data Lake Solution, designed to accelerate AI adoption across industries. Peter Zhou, Vice President of Huawei and President of Huawei Data. Together with NVIDIA and SAP, Deutsche Telekom is building an Industrial AI Cloud on German soil. This is a strong signal for the digital sovereignty and industrial competitiveness of Germany and Europe. As early as the first quarter of 2026. Germany's AI servers and GPU hardware market is emerging as a strategic component of Europe's broader digital transformation agenda. Germany has launched one of Europe's largest AI factories, hoping to position the country - and the European Union - as a major player in.
[PDF Version]
-
Multi-channel AI Server
In this guide, you'll learn how to architect a Multi-Channel Processing (MCP) server using FastAPI and LangChain. This setup is ideal for projects involving LLMs and AI agents, where performance, modularity, and extensibility matter. 🚀 Why FastAPI + LangChain?OpenClaw is a self-hosted gateway that connects WhatsApp, Telegram, Discord, and iMessage to AI coding agents. You run one Gateway process on your machine, and it becomes the bridge between your messaging apps and an AI assistant you control. OpenClaw installed and running. A configuration file (usually. OpenClaw's multi-agent routing lets you run a whole team of specialized AI agents — each with their own personality, memory, and skills — all from a single server. This. Our stack prioritizes performance, reliability, and scalability, serving as the foundation for teams shipping production-grade autonomous systems.
[PDF Version]
-
COMSOL Simulation of Fiber Optic Sensors
In this video, we demonstrate a step-by-step simulation of Single Mode Optical Fiber using COMSOL Multiphysics. You'll learn how to model the fiber structure, set up boundary conditions, select a. moreThe transmission speed of optical waveguides is superior to microwave waveguides because optical devices have a much higher operating frequency than microwaves, enabling a far higher bandwidth. Designed for students, researchers, and engineers in photonics, this course takes you step-by-step from building simple step-index. For which radius do you have a single mode fiber? How can you assign the nomenclature of each mode ? Which ones are TE? TM? EH/HE? What are the values for n and m?.
[PDF Version]
-
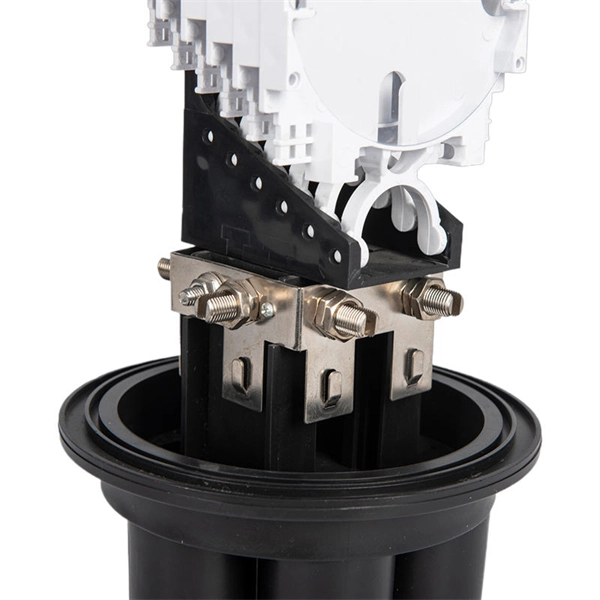
Methods for cooling down network server racks
To cool your server rack, ensure proper airflow by organizing cables, using fans, and maintaining optimal room temperature. Implementing hot aisle/cold aisle containment can also enhance cooling efficiency. Passive cooling – for low-density, climate-controlled environments. Modern servers generate substantial heat during normal operation, and this thermal output only increases as you add more equipment to your racks. They house the powerful computing machines that keep businesses, websites, and cloud services running 24/7. Managing that heat through efficient server rack cooling is essential not just for. Server rack cooling is a system and method used to remove the heat generated by servers and IT equipment within the rack.
[PDF Version]
-
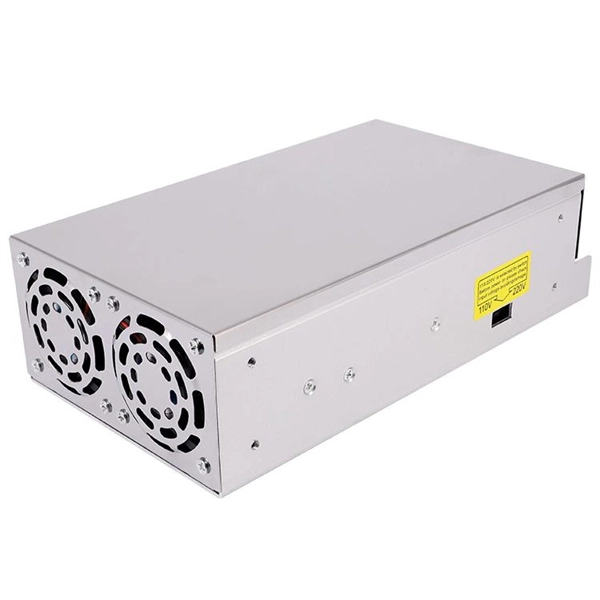
Does AI computing infrastructure require liquid-cooled servers
The next generation of AI servers pushes the bounds of computational power at the cost of increasing power consumption, requiring the use of liquid cooling. Liquid cooling has become a critical enabler for modern AI data centers as facilities scale to handle high-density workloads, such as artificial intelligence (AI) and machine learning. Air is a fundamentally poor thermal conductor. To prevent processors from. At CES 2026, NVIDIA unveiled its next-generation Rubin platform, building on the liquid-cooled Blackwell architecture and designed to operate with warm-water supply loops around 45°C.
[PDF Version]