Related Topics:
Local Inference Server 2026-
How many watts does an AI server consume
A fully populated AI server rack with eight high-performance GPUs, dual CPUs, networking cards, and storage can easily consume 12-15 kilowatts of continuous power. GPUs for AI ran at 400 watts until 2022, while 2023 state-of-the-art GPUs for generative AI run at 700 watts, and 2024 next-generation chips are expected to run at 1,200 watts. The average power density is anticipated to increase from 36 kilowatts per server rack in 2023 to 50 kilowatts per rack by. The average AI rack costs $3. Sources: Uptime Institute 2020/2024 Surveys, Ramboll US data centers consumed 176 TWh in 2023, representing 4. By 2024, that rose to approximately 183. In 2023, U. This comprehensive guide explores exactly how much electricity data centers use, what drives their enormous energy appetite, and what the future holds as. Global electricity consumption from data centers reached approximately 415 terawatt-hours (TWh) in 2024, representing about 1. This figure is projected to more than double by 2030, reaching between 945 TWh and 1,050 TWh.
[PDF Version]
-
P40 multi-GPU AI server
We've built a homeserver for AI experiments, featuring 96 GB of VRAM and 448 GB of RAM, with an AMD EPYC 7551P processor. We'll be testing our Tesla P40 GPUs on various LLMs and CNNs to explore their performance capabilities. We'll also share our approach to cooling these GPUs. more Audio tracks. Tesla P40 24GB for possible local AI server build. 0 16x lanes, 4GB decoding, to locally host a 8bit 6B parameter AI chatbot as a personal project. Would. This guide details the configuration steps required to properly set up multiple Tesla P40 GPUs in passthrough mode for Ollama on an Ubuntu 22. 04 VM running on a Proxmox host. Edit your VM configuration file (/etc/pve/qemu-server/YOUR_VM_ID. It runs 30B+ models that gaming GPUs under $200 can't touch. The catch: no display output, no fans, no native FP16, and you'll need a cooling mod. Pre-installed NVIDIA drivers, Linux/Windows support, and flexible CPU–Memory–GPU combinations make it ideal for AI training, inference, rendering, and scientific computing. Equipped with a substantial 24 GB of GDDR5 VRAM, this GPU is an intriguing option for those looking to run local text generation models.
[PDF Version]
-
Huawei AI Server Liquid Cooling
Huawei developed a full liquid cooling solution, reducing the power consumption by 96% and cutting the PUE from 2. This increase in power density has posed an unprecedented challenge to conventional cooling systems. To address this challenge, Huawei. Advanced AI chips are generating more heat in data centers, necessitating improved cooling solutions. Proposed techniques include circulating water through cold plates, circulating boiling liquid through cold plates. Liquid cooling is essential for AI-driven data centres, efficiently managing the extreme heat generated by high-density AI server racks. It offers up to 15% better energy efficiency and reduces cooling costs compared to traditional air-cooling systems The technology also enables higher server. This AI revolution is built on incredibly powerful computer chips. But there's a catch, a hot one. These chips, especially the GPUs that are the workhorses of AI, are generating a staggering amount of heat.
[PDF Version]
-
AI call not connected to server
Call reconnect(failed_only=True) to retry failed servers, or reconnect(failed_only=False) to restart all servers. I have two agents deployed in Azure AI Foundry (Switzerland North), both using a shared GPT-4. 1 model deployment: Agent 1: apples-agent Has an MCP server configured The MCP server exposes one tool: returns the number of apples in my basket Works correctly when invoked directly - returns expected. When I try to setup the connection in the playground it seems to take a long time to connect to the MCP server (if it really is, not sure) and then goes to the page to list the tools and errors out with “Unable to load tools”. MCP Server just has a single function to create a file Server Implementation @Tool(name = "Create File", description = "Create a file with the provided fileName on the file system") public String createFile(String fileName) {. Make sure you call 'connect ()' first. UserError: Server not initialized. Make sure you call 'connect ()' first. · Issue #446 · openai/openai-agents-python /agents/mcp/server.
[PDF Version]
-
How many watts does a network server rack need
A standard 42U rack typically draws 4–12 kW for enterprise workloads, while high-density GPU/TPU racks can exceed 30–50 kW. Critical factors include server configurations (e. 1U), redundancy (N+1/2N), and cooling overhead (≈40% of IT load). Free server power calculator to estimate rack power draw, daily and monthly kWh, energy cost, PUE impact, and cooling load for data centers and server rooms. Use measured or nameplate × utilization (e. Ignoring it can lead to higher expenses, overheating, and even system failures. The best way to find this value is to divide your server's power supply, or server watts, by your facility power (VAC).
[PDF Version]
-
How much is 1u in a network server rack
A Rack Unit (U or RU) is the standard height measurement used for mounting equipment in server racks. 5 inches tall, a 4U device is 7 inches tall, and so on. This article explains definition, planning, installation tips, and trends. 45 mm), making it easy to size and organize hardware in a consistent, stackable way. Whether you're building a server setup or an energy storage. You'll instantly know how tall your server rack needs to be—and whether your gear will fit—once you understand that 1U = 1.
[PDF Version]
-
How to make an outdoor server room look good
In fact, the first three design moves make the biggest immediate difference: organize every cable with color-coded systems, fine-tune lighting to daylight quality LEDs, and introduce acoustic or artistic features that double as functional tools. Outdoor dining is more than just a meal under the sky; it's an experience that blends nature, aesthetics, and comfort. Whether you're hosting garden parties, enjoying a minimalist brunch, or planning a luxury dinner, the right outdoor table decor can transform your patio into a stylish oasis. When you host an event outside, the possibilities are wide open—literally. Whether it's a backyard wedding. Server decorating ideas aren't just about hiding cables or maximizing rack efficiency—they're a real opportunity to redefine productivity, morale, and even security in spaces typically ignored. Drawing from a decade of hands-on experience, I've seen firsthand how a few thoughtful upgrades transform. Are you tired of staring at a dull and disorganized server room? It's time to transform your space into something visually appealing and efficient.
[PDF Version]
-
Performance Comparison of New Fiber Optic Terminal Boxes and How to Choose Them
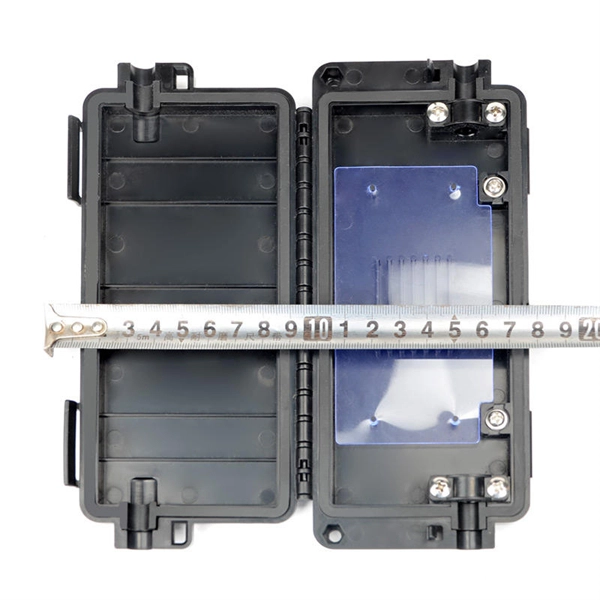
Discover how to select the best fiber optic terminal box for data centers, campus fiber backbones, outdoor FTTH networks, and enterprise fiber systems. Learn how environment, capacity, splicing, connector compatibility, and long-term reliability shape your choice of. FAT, FDB, and CTO boxes are three common types of fiber termination and distribution hardware used in FTTH and outdoor access networks. Their differences lie in internal structure, cable routing capacity, waterproofing, port configuration, and whether they support pre-connectorized or splice-based. In every fiber build, there's a quiet place where the glass path meets the real world: the fiber optic terminal box. It's where delicate strands are protected, splices are routed, connectors are exposed for patching, and future changes are made painless—or painful. Fiber optic terminal boxes, also known as optical distribution boxes, serve as pivotal. The IP65 rated fiber optic termination boxes, such as compact 8-port models, excel in both indoor and outdoor settings by shielding connections from dust and water. Understanding how these devices work together helps.
[PDF Version]
-
How to Choose a Microscope Spectrometer
Selecting the right spectrometer involves understanding key features such as sensitivity, speed, and resolution, along with the wavelength range and measurement techniques. For Raman you can use our RamanShift calculator to convert back and forth between nm and cm-1. This blog post will explore these factors, discuss the importance of size, price, and performance, and describe different. How to Choose the Right Spectrometer? A spectrometer is a measuring device that allows you to decompose and analyze the elementary components that make up the spectrum of a radiation or ion beam. High sensitivity ensures accurate results even in challenging environments, where signals. Microspectrophotometry or Microspectroscopy combines the visualization of a standard microscope with the analytical tools of a spectrophotometer for material characterization on a microscopic scale.
[PDF Version]